End-to-end tracing
Every model call, tool call, retrieval step and side effect in one trace, tagged with prompt version and run metadata, so a bad answer leads straight to its cause.
We set up LangSmith tracing, evaluation datasets and regression checks for LangChain and LangGraph agents, so every prompt, model or retrieval change is tested before it ships. Built by official LangChain Ambassadors and Experts.
 LangChain experts
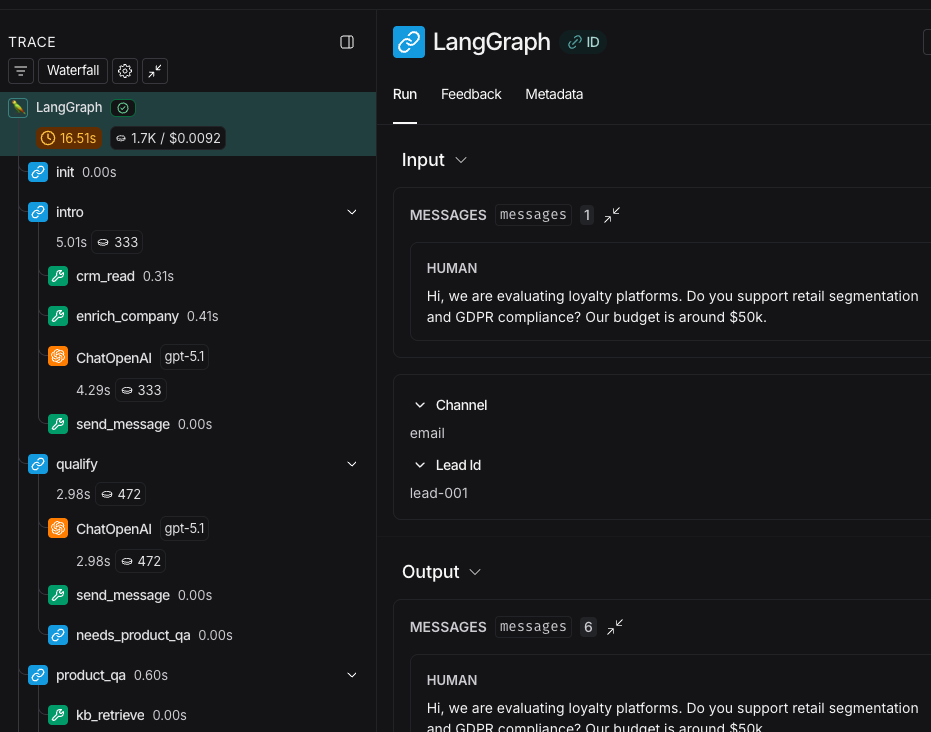
Every model call, tool call, retrieval step and side effect in one trace, tagged with prompt version and run metadata, so a bad answer leads straight to its cause.
A dataset built from real conversations, scored on routing, grounding and field extraction, and run against every prompt, model or retrieval change.
LLM-as-judge evaluators checked against human labels before their scores are allowed to decide a release.
Failures from live traffic are classified, queued for repair and added to the dataset, so each production problem becomes the next release's test. LangSmith Engine can now cluster those failures into issues on its own; we still read the traces.
Soba Labs instruments your LangChain or LangGraph agent with LangSmith tracing, builds an evaluation dataset from real conversations, writes the evaluators that score it, and wires the results into your release process, so a prompt, model or retrieval change ships only after it passes the same checks as the last one.
We score the whole sequence, not only the final message: whether the agent routed correctly, extracted the required fields, stayed grounded in approved sources and avoided an unsafe or duplicate side effect. Each check runs on a LangSmith dataset, and each meaningful change is compared with the previous run on the same examples. Read the Open Loyalty case study for a worked example.
Logs show individual calls. LangSmith groups every step of one operation into a trace, so you can see what retrieval returned, which prompt version ran and which tool call caused a side effect, and the same traces feed the datasets and evaluators that test the next release.
Yes. Most engagements start from a running agent. We add tracing first, read real runs to find where quality breaks, and turn those failures into the first evaluation set, in your environment and with your team.
As of October 2026, LangSmith is a platform with several more parts. Deployment runs LangGraph agents as an Agent Server, in LangChain's cloud, in a hybrid setup or self-hosted. Engine (public beta) watches production traces, clusters recurring failures into issues, diagnoses them against your code and proposes a fix. LLM Gateway (beta) sits between the agent and the model providers with spend caps, rate limits and model fallbacks. Sandboxes run agent-generated code in isolation. Fleet is no-code agents for non-developers, which we do not build on. We bring in the first four where they shorten the path to a reliable release.
LangSmith Cloud has US, EU and APAC regions; the EU region runs in GCP europe-west4 in the Netherlands with its own endpoint, so an organization created there keeps traces, datasets and deployments in the EU (as of October 2026). A self-hosted LangSmith on your own Kubernetes keeps everything inside your network and is an Enterprise plan add-on. We set the region or the self-hosted install up before the first trace is sent, since a region cannot be changed afterwards. How we pick the hosting option: production deployment.
Like every Soba Labs engagement: a fixed price on a defined outcome, agreed before we start. You own the traces, datasets, evaluators and code.
The reasoning core of a multi-agent localisation pipeline: a structured client rule base, the agents that reason over it, and producer approval at key decision points.
A production sales agent that qualifies inbound leads, answers product questions from a live knowledge base, and writes structured outcomes back to the CRM.
A patient-facing assistant that explains health scan results from an approved medical knowledge base. Low-confidence and clinical questions route to a clinician.
1/1
We sell a fixed price on a defined outcome, delivered in days. Every system is custom to your process and your data, and you own it and its source. No product to license, no platform to rent, no lock-in.
Book a consultation